ULTIMI_
Tutti i post in ordine cronologico inverso
[01] novembre 2026
Benchmark
Claude Fable 5.2 vs Opus 5.5: prezzo, benchmark e quale scegliere
Benchmark
AI senza censura? 9 modelli messi alla prova con 16 domande
Benchmark
llms.txt: i bot AI lo leggono davvero? I dati dei log
Benchmark
Quale IA usare per fisica? Gemini, ChatGPT e il test sul lancio verticale
Benchmark
GPT-Image-2.6 e videogiochi: una scena in 10 stili
Benchmark
Gemini Omni 1.2: movimenti di camera, volo FPV e rotazioni
Benchmark
Gemini Omni 1.2 vs 1.1: prompt identici a confronto

Benchmark
Gemini Omni 1.2 vs Seedance, Kling, Veo e Wan: test video AI
Benchmark
Gemini Omni 1.2 Flash: il mio test al lancio con video di 15 secondi
Benchmark
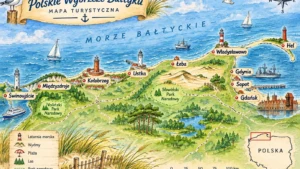
GPT-Image-2.6 contro Nano Banana 2.1, FLUX 3, Seedream e Qwen
Benchmark
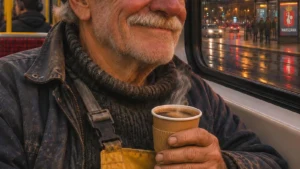
GPT-Image-2.6 vs 2.5: stessa tariffa, costo triplo
Benchmark
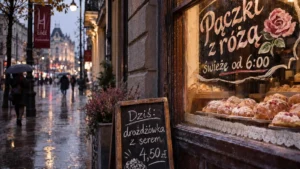
GPT-Image-2.6: Flare o Sunburst? Stesso costo, tempi diversi
Benchmark
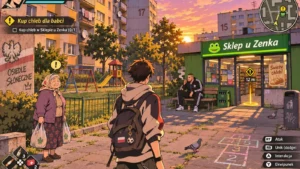
ChatGPT Images 2.6: test su oltre 130 immagini, Flare e Sunburst
Benchmark
Honeypot per agenti AI: il test per il rispetto dello scope
Benchmark
GPT-6 Cyber: tutti i benchmark della scheda di sistema
[02] ottobre 2026
Benchmark
Test AI: Claude Opus 5, GPT-6 Astra e altri 5 modelli a confronto
Benchmark
Gemini 4 Argon vs Gemini 3.1 Pro: cosa cambia e quale scegliere
Benchmark
Mercury Decide e Celeris-1: confronto tra velocità e prezzi
Benchmark
COPEX: come si manipolano i modelli linguistici nei sistemi MCP
Benchmark
Gemini 4 Argon per programmare: test e benchmark
Benchmark
basal-omni: primo tra i modelli aperti su JevBench
Benchmark
basal-omni in locale: test con Ollama, llama.cpp e Mac
Benchmark
Liquid AI d1-ultra: prezzo e test del modello decisionale
Benchmark
Perplexity Decider v1.1 27B: prezzo, test e benchmark
// mappa del sito
×
‹
![ingrandimento]() ›